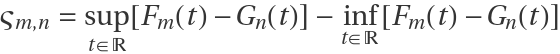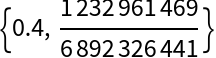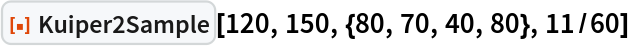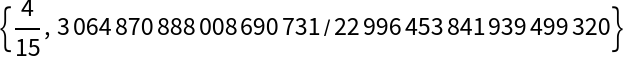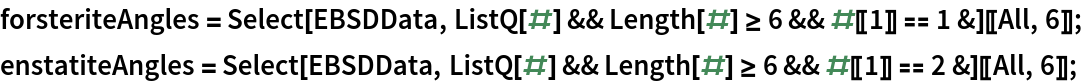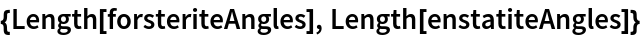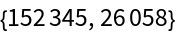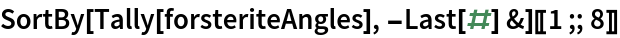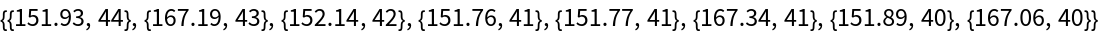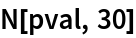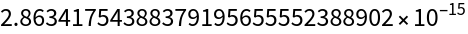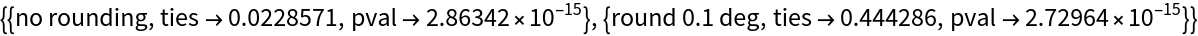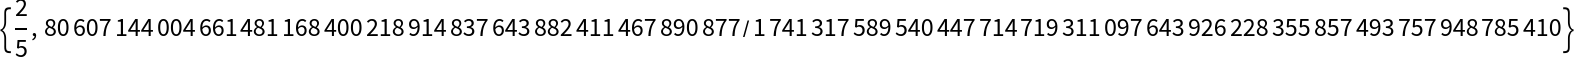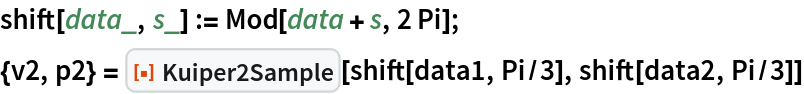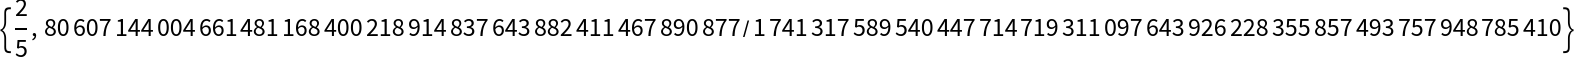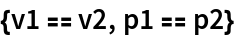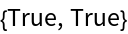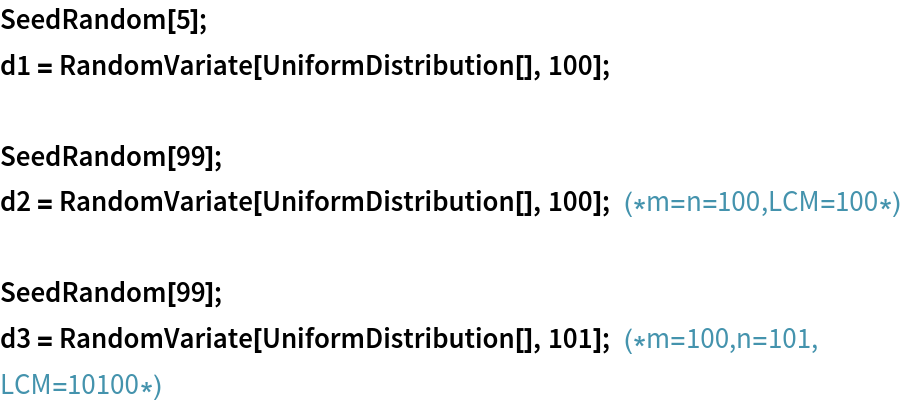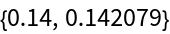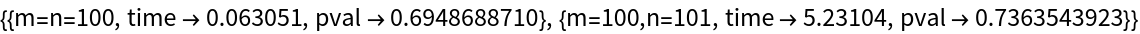Function Repository Resource:

 Kuiper2Sample

Compute the exact p-value of the two-sample Kuiper test for arbitrary data on the real line or circle with possible ties

Contributed by: Dimitrina S. Dimitrova, Yun Jia & Vladimir K. Kaishev

ResourceFunction["Kuiper2Sample"][data1,data2]

returns {v,p}, the observed Kuiper statistic and exact p-value, for samples data1 and data2.

ResourceFunction["Kuiper2Sample"][m,n,q]

returns the exact p-value P(Vm+n≥q) given sample sizes m,n and observed statistic q.

ResourceFunction["Kuiper2Sample"][m,n,multiplicity,q]

uses the multiplicity vector multiplicity for data with ties.

Details

This is the Wolfram Language counterpart of Kuiper2sample and Kuiper2sample_Rcpp in the R package KSgeneral.
Unlike most existing implementations, which require continuous data and equal sample sizes, this function handles arbitrary continuous, discrete, or mixed data including ties. See Maag and Stephens (1968) and Hirakawa (1973) for the equal-sample-size continuous case.
Kuiper2Sample[data1,data2] tests the null hypothesis H0:F(x)=G(x) for all x against H₁:F(x)≠G(x) where F and G are the unknown underlying CDFs of data1 and data2 respectively. Both samples may come from continuous, discrete or mixed distributions and may contain ties.
The Kuiper statistic is defined as , where Fm(t) and Gn(t) are the empirical CDF of the data1 and data2. It is invariant to cyclic shifts, making it ideal for circular and seasonal data and uniformly sensitive across the full support of the distribution.
The p-value is the exact conditional probability P(Vm+n≥q|Zm+n), where Vm+n is permutation version of the Kuiper statistic ςm,n obtained by randomly repartitioning the pooled sample Zm+n={data1,data2} into two groups of sizes m and n. By Theorem 2.6 of Dimitrova, Jia, Kaishev (2026), this permutation p-value is asymptotically consistent with the unconditional p-value for arbitrary underlying distributions F and G.

The data-interface form Kuiper2Sample[data1,data2] returns the list {v,p} where v is the observed Kuiper statistic and p is the exact rational p-value. The low-level form Kuiper2Sample[m,n,M,q] returns only the p-value.
In the low-level form, multiplicity is an integer list of length k (the number of distinct values in the pooled sample) where multiplicity[[i]] is the number of times the i-th distinct pooled-sample value appears. Total[multiplicity] must equal m+n. When there are no ties, multiplicity=ConstantArray[1,m+n]. The parameter q must lie in[0, 2].
The p-value P(Vm+n≥q) is computed via the permutation formulation of Proposition 2.7 of Dimitrova, Jia, Kaishev (2026), which expresses N as an alternating sum of one-sided trajectory counts N(a,b), each computed by the KS recurrence with asymmetric bounds. The simplified formula of Remark 2.8 of Dimitrova, Jia, Kaishev (2026) is used when q > 1.
The worst-case complexity is O(mn*r), where r= GCD[m,n]; when r is large (e.g. m=n), it reduces to O(m²n).

Examples

Basic Examples (3) 

Two samples of size 20 drawn from the same uniform distribution:

In[1]:=
SeedRandom[1];
data1 = RandomVariate[UniformDistribution[], 20];
data2 = RandomVariate[UniformDistribution[], 20];
ResourceFunction["Kuiper2Sample"][data1, data2]
Out[4]=

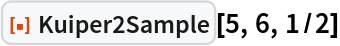
Simplest low-level call: no ties, exact rational p-value:

In[5]:=
ResourceFunction["Kuiper2Sample"][5, 6, 1/2]
Out[5]=

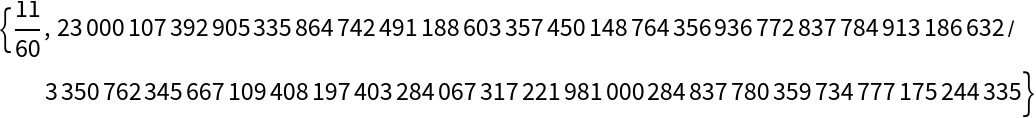
Use the multiplicity vector to indicate how many pooled-sample values are tied at each distinct value; here m=120,n=150 with four groups of tied observations at q=11/60:

In[6]:=
ResourceFunction["Kuiper2Sample"][120, 150, {80, 70, 40, 80}, 11/60]
Out[6]=

Scope (2) 

For discrete circular data with ties, the Kuiper test is well-suited to circular data because its statistic is invariant to the choice of origin on the circle:

In[7]:=
data1 = Join[ConstantArray[Pi/2, 30], ConstantArray[Pi, 30], ConstantArray[3 Pi/2, 30], ConstantArray[2 Pi, 30]];
data2 = Join[ConstantArray[Pi/2, 50], ConstantArray[Pi, 40], ConstantArray[3 Pi/2, 10], ConstantArray[2 Pi, 50]];
ResourceFunction["Kuiper2Sample"][data1, data2]
Out[9]=

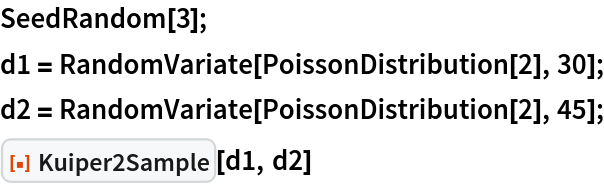
Unequal sample sizes with ties from discrete distributions:

In[10]:=
SeedRandom[3];
d1 = RandomVariate[PoissonDistribution[2], 30];
d2 = RandomVariate[PoissonDistribution[2], 45];
ResourceFunction["Kuiper2Sample"][d1, d2]
Out[13]=

Applications (11) 

Load the MTEX Forsterite EBSD (Electron Backscatter Diffraction) dataset. The dataset contains 178,403 crystallographic measurements from a polished peridotite thin section (Bachmann, Hielscher, Schaeben, 2010; GPL-2.0; available at https://github.com/mtex-toolbox/mtex/tree/develop/data/EBSD), including phase labels, spatial coordinates, Euler angles, and EBSD quality metrics (columns: Phase, x, y, Bands, Error, φ₁, φ₂, φ₃, MAD, BC, BS):

In[14]:=
(* Evaluate this cell to get the example input *) CloudGet["https://www.wolframcloud.com/obj/fd4983b3-f364-48c9-8347-4772b437faa2"]

Extract the φ₁ Euler angle for each mineral phase. Column 6 contains φ₁ in degrees. Separate the measurements into Forsterite (phase 1) and Enstatite (phase 2) for subsequent comparison of their angular distributions:

In[15]:=
forsteriteAngles = Select[EBSDData, ListQ[#] && Length[#] >= 6 && #[[1]] == 1 &][[All, 6]];
enstatiteAngles = Select[EBSDData, ListQ[#] && Length[#] >= 6 && #[[1]] == 2 &][[All, 6]];

Verify the number of measurements in each phase. The resulting subsets contain 152,345 Forsterite measurements and 26,058 Enstatite measurements:

In[16]:=
{Length[forsteriteAngles], Length[enstatiteAngles]}
Out[16]=

List the eight most frequently repeated φ₁ values in the Forsterite data. Maximum repeat count is 44, indicating moderate concentration around particular orientations:

In[17]:=
SortBy[Tally[forsteriteAngles], -Last[#] &][[1 ;; 8]]
Out[17]=

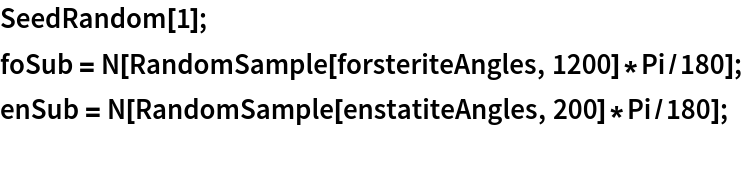
The full dataset (M = 152,345 Forsterite, N = 26,058 Enstatite) is too large to run the exact test directly. Draw a reproducible subsample of m = 1200 and n = 200, preserving the original ~6:1 phase ratio:

In[18]:=
SeedRandom[1];
foSub = N[RandomSample[forsteriteAngles, 1200]*Pi/180];
enSub = N[RandomSample[enstatiteAngles, 200]*Pi/180];

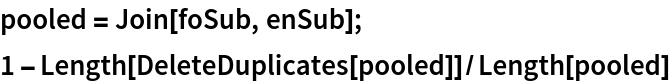
Approximately 2.3% of the pooled subsample observations are tied, confirming that exact tie-handling is necessary:

In[19]:=
pooled = Join[foSub, enSub];
1 - Length[DeleteDuplicates[pooled]]/Length[pooled]
Out[20]=

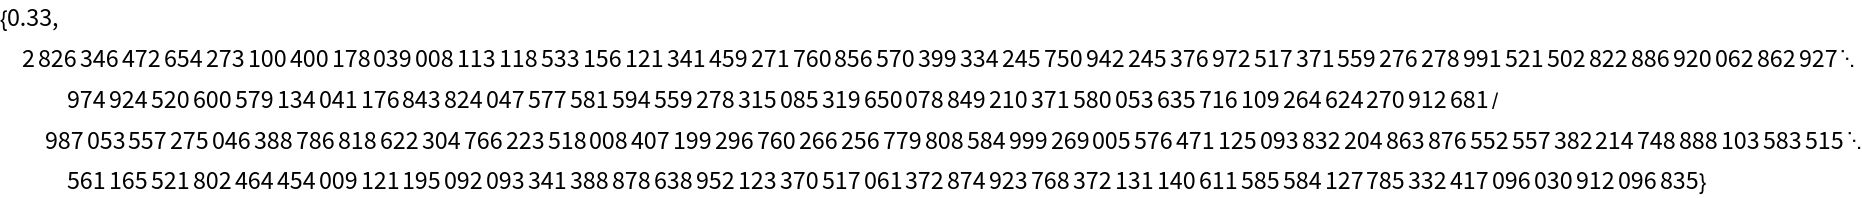
Compare the two circular φ₁ distributions using the two-sample Kuiper test, which is invariant to the choice of angular origin:

In[21]:=
{vstat, pval} = ResourceFunction["Kuiper2Sample"][foSub, enSub]
Out[21]=

Exact p-value evaluated to 30 significant digits:

In[22]:=
N[pval, 30]
Out[22]=

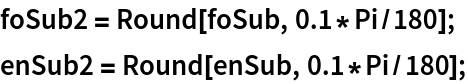
To assess the robustness of the exact tie-handling, round the subsample angles to 0.1° — within typical EBSD angular measurement precision — artificially increasing the proportion of tied observations while keeping the same data:

In[23]:=
foSub2 = Round[foSub, 0.1*Pi/180];
enSub2 = Round[enSub, 0.1*Pi/180];

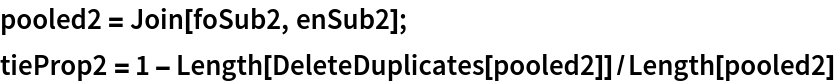
The tie proportion increases from 2.3% to 44.7% after rounding:

In[24]:=
pooled2 = Join[foSub2, enSub2];
tieProp2 = 1 - Length[DeleteDuplicates[pooled2]]/Length[pooled2]
Out[25]=

Apply the Kuiper test to the rounded subsample. The p-value is virtually unchanged despite the large increase in ties, confirming that exact tie-handling leaves the inference unaffected:

In[26]:=
{vstat2, pval2} = ResourceFunction["Kuiper2Sample"][foSub2, enSub2]; 
{{"no rounding", "ties" -> N[4/175], "pval" -> N[pval, 6]}, {"round 0.1 deg", "ties" -> N[tieProp2], "pval" -> N[pval2, 6]}}
Out[27]=

Properties and Relations (3) 

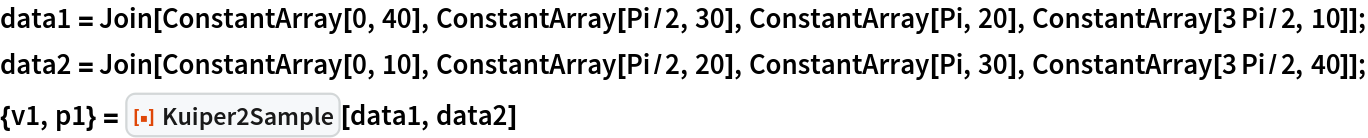
The Kuiper statistic is invariant to cyclic shifts of the data. Shifting data1 and data2 by an arbitrary constant on the circle leaves the Kuiper statistic and p-value unchanged.

Four equally spaced mass points on[0, 2π) with unequal observation counts:

In[28]:=
data1 = Join[ConstantArray[0, 40], ConstantArray[Pi/2, 30], ConstantArray[Pi, 20], ConstantArray[3 Pi/2, 10]];
data2 = Join[ConstantArray[0, 10], ConstantArray[Pi/2, 20], ConstantArray[Pi, 30], ConstantArray[3 Pi/2, 40]];
{v1, p1} = ResourceFunction["Kuiper2Sample"][data1, data2]
Out[29]=

Shift every observation by π/3 on the circle and retest:

In[30]:=
shift[data_, s_] := Mod[data + s, 2 Pi];
{v2, p2} = ResourceFunction["Kuiper2Sample"][shift[data1, Pi/3], shift[data2, Pi/3]]
Out[5]=

The Kuiper statistic and p-value are exactly preserved under the cyclic shift:

In[31]:=
{v1 == v2, p1 == p2}
Out[32]=

Possible Issues (4) 

Random variables d2 and d3 are drawn from the same seed so they have nearly identical Kuiper statistics against d1; the timing difference is due to LCM[m,n] alone:

In[33]:=
SeedRandom[5];
d1 = RandomVariate[UniformDistribution[], 100];

SeedRandom[99];
d2 = RandomVariate[UniformDistribution[], 100];   (*m=n=100,LCM=100*)

SeedRandom[99];
d3 = RandomVariate[UniformDistribution[], 101];   (*m=100,n=101,LCM=10100*)

Confirm the statistics are close:

In[34]:=
{ResourceFunction["Kuiper2Sample"][d1, d2][[1]], ResourceFunction["Kuiper2Sample"][d1, d3][[1]]}
Out[35]=

Complexity is O(mn*r), where r= LCM[m,n]. When m=n,LCM[m,n]=m so complexity is O(m3). When m and n are coprime (e.g. m=n+1), LCM[m,n]=mn and complexity is O(m2n2), which is much larger. For larger samples consider the R package KSgeneral which uses a compiled C++ implementation:

In[36]:=
{t2, {vstat2, pval2}} = AbsoluteTiming[ResourceFunction["Kuiper2Sample"][d1, d2]];
{t3, {vstat3, pval3}} = AbsoluteTiming[ResourceFunction["Kuiper2Sample"][d1, d3]];

Timing and p-values for both cases:

In[37]:=
{{"m=n=100", "time" -> t2, "pval" -> N[pval2, 10]}, {"m=100,n=101", "time" -> t3, "pval" -> N[pval3, 10]}}
Out[38]=

Publisher

Yun Jia

Requirements

Wolfram Language 13.0 (December 2021) or above

Version History

  • 1.0.0 – 02 October 2026

Source Metadata

Related Resources

Author Notes

Kuiper2sample implements the exact algorithm of Proposition 2.7 and Remark 2.8 of Dimitrova, Jia, Kaishev (2026), which extends the Nikiforov (1994) recurrence to handle the joint one-sided bounds needed for the Kuiper statistic. Prior exact formulas (Maag and Stephens 1968; Hirakawa 1973) required equal sample sizes and continuous data. This implementation handles arbitrary m,n and tied observations. The kuiperks helper function uses a boundary offset of 10⁻⁹ in deviatUp and deviatDown. This enforces the strict inequality convention (D⁺ < a, D⁻ < b) consistent with the original Nikiforov Fortran code and its C++/R descendants. Removing it would cause off-by-one errors at lattice boundary values of q.

License Information