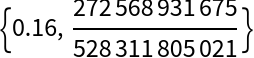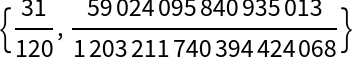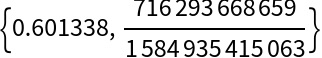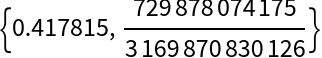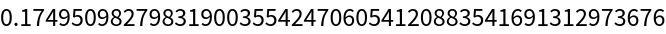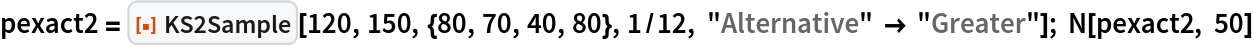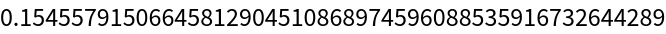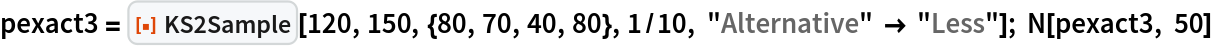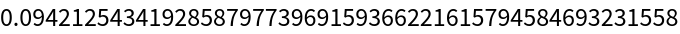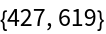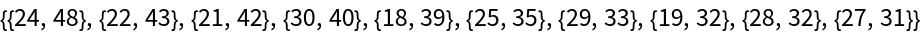Function Repository Resource:

 KS2Sample

Source Notebook

Compute the exact p-value of the weighted two-sample Kolmogorov-Smirnov test for arbitrary data with possible ties

Contributed by: Dimitrina S. Dimitrova, Yun Jia & Vladimir K. Kaishev

ResourceFunction["KS2Sample"][data1,data2]

returns {d,p}, the observed KS statistic and exact p-value, for samples data1 and data2.

ResourceFunction["KS2Sample"][m,n, q]

returns the exact (complementary) cdf P(Dm,n≥q) for sample sizes m and n with no ties.

ResourceFunction["KS2Sample"][m,n,multiplicity,q]

uses the multiplicity vector multiplicity for data with ties.

Details

This is the Wolfram Language counterpart of KS2sample and KS2sample_Rcpp in the R package KSgeneral (Dimitrova, Jia, Kaishev 2026).
Unlike the R version, which uses floating-point arithmetic and requires a tolerance parameter, the Wolfram Language implementation is designed for exact arithmetic throughout and returns an exact rational p-value.
KS2Sample[data1,data2, …] tests the null hypothesis H0: F(x) = G(x) for all x, where F and G are the unknown underlying CDFs of data1 and data2 respectively. Both samples may come from continuous, discrete, or mixed distributions and may contain repeated observations (ties).
The two-sample KS statistics are (two-sided), (one-sided greater), and (one-sided less), where Fm(t), Gn(t) and Em+n⁡(t) are the empirical CDF of the data1, data2 and the pooled sample Zm+n={data1, data2} respectively and W is the weight function.
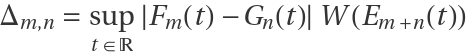
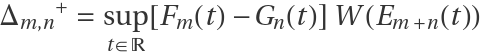
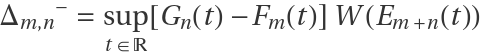
The option "Alternative" controls the direction of the test. "TwoSided" (default) uses Δm,n; "Greater" uses Δm,n+ to test H1: F(x) > G(x); "Less" uses Δm,n- to test H1: F(x) < G(x).weight=Function[t,1/Sqrt[t(2-t)]]
The option "Weight" controls the weight function W. "Weight"→ 0 (default) gives the standard unweighted KS test (W(t)=1). "Weight"→ν, for ν ∈ (0, 1], gives the parametric family W(t) = 1/[t(1−t)])ν due to Finner and Gontscharuk (2018); ν = 0.5 recovers the Anderson-Darling weight of Canner (1975). A user-supplied function enables arbitrary weights, e.g. “Weight”→ Function[t,1/Sqrt[t(2-t)]] for the Büning (2001) weight suited to left-skewed heavy-tailed data.
The data-interface form ResourceFunction["KS2Sample"][data1, data2, …] returns the list {d,p} where d is the observed KS statistic and p is the exact rational p-value. The low-level form ResourceFunction["KS2Sample"][m,n,multiplicity,q] returns only the p-value as an exact rational number.
In the low-level form, multiplicity is an integer list of length k (the number of distinct values in the pooled sample) where multiplicity[[i]] is the number of times the i-th distinct pooled-sample value appears. Total[multiplicity] must equal m+n. When there are no ties, multiplicity=ConstantArray[1,m+n]. The weight function is specified via the "Weight" option. It is evaluated at i/(m+n) for i = 1, …, m+n-1 internally.
The p-value is the exact conditional probability P(Dm,n≥q|Zm+n), where Dm,n is permutation version of the selected KS statistic (Δm,n, Δm,n+ or Δm,n-) obtained by randomly repartitioning the pooled sample Zm+n into two groups of sizes m and n. By Theorem 2.1 of Dimitrova, Jia, Kaishev (2026), this permutation p-value is asymptotically consistent with the unconditional p-value for arbitrary underlying distributions F and G.
The algorithm implements the recurrence Bs(i,j)=1s(i,j)[Bs(i-1,j)+Bs(i,j-1)] on the integer grid R = {(i,j): 0 ≤ i ≤ m, 0 ≤ j ≤ n}, where S is the region defined by d(i,j)< q. It runs in O(m n) time, processes one anti-diagonal per iteration, and uses vectorised slice assignment for the inner update. All arithmetic is exact; no floating-point tolerance is required.
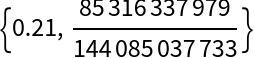
Examples

Basic Examples (3) 

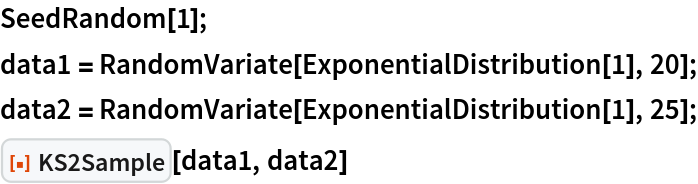
Two samples of size 20 and 25 drawn from the same exponential distribution:

In[1]:=
SeedRandom[1];
data1 = RandomVariate[ExponentialDistribution[1], 20];
data2 = RandomVariate[ExponentialDistribution[1], 25];
ResourceFunction["KS2Sample"][data1, data2]
Out[4]=

Small exact example with no ties. All inputs are exact integers or rationals:
In[5]:=
ResourceFunction["KS2Sample"][5, 6, 3/10]
Out[5]=
In[6]:=
ResourceFunction["KS2Sample"][5, 6, 3/10, "Alternative" -> "Greater"]
Out[6]=

Low-level call with tied observations; m=120, n=150, four groups of ties, q=1/10 (example from Nikiforov 1994):

In[7]:=
ResourceFunction["KS2Sample"][120, 150, {80, 70, 40, 80}, 1/10]
Out[7]=

Scope (5) 

One-sided test: checks whether data1 tends to produce larger values than data2, i.e. H1: F(x) > G(x):

In[8]:=
SeedRandom[1];
data1 = RandomVariate[ExponentialDistribution[1], 20];
data2 = RandomVariate[ExponentialDistribution[1], 25];
ResourceFunction["KS2Sample"][data1, data2, "Alternative" -> "Greater"]
Out[9]=

Discrete data with ties: both samples come from Poisson distributions. The exact computation correctly accounts for the repeated values:

In[10]:=
SeedRandom[2];
data3 = RandomVariate[PoissonDistribution[2], 30];
data4 = RandomVariate[PoissonDistribution[3], 40];
ResourceFunction["KS2Sample"][data3, data4]
Out[11]=

Anderson-Darling weight (ν = 1/2): gives more weight to differences in the tails of the distribution than the standard unweighted test:

In[12]:=
SeedRandom[1];
data1 = RandomVariate[ExponentialDistribution[1], 20];
data2 = RandomVariate[ExponentialDistribution[1], 25];
ResourceFunction["KS2Sample"][data1, data2, "Weight" -> 1/2]
Out[13]=

Buning (2001) weight W(t) = 1/Sqrt[t(2-t)], recommended when both samples are expected to come from left-skewed heavy-tailed distributions:

In[14]:=
ResourceFunction["KS2Sample"][data1, data2, "Weight" -> Function[t, 1/Sqrt[t (2 - t)]]]
Out[14]=

Low-level call with Anderson-Darling weight and tied data:

In[15]:=
ResourceFunction["KS2Sample"][10, 12, ConstantArray[1, 22], 0.8, "Weight" -> 1/2]
Out[15]=

Applications (4) 

Examples in Nikiforov (1994), two sided exact rational p-value:

In[16]:=
pexact = ResourceFunction["KS2Sample"][120, 150, {80, 70, 40, 80}, 1/10]
Out[16]=

Rational p-value evaluated to 50 digits:

In[17]:=
N[pexact, 50]
Out[17]=

One-sided "Greater" test at q=1/12:

In[18]:=
pexact2 = ResourceFunction["KS2Sample"][120, 150, {80, 70, 40, 80}, 1/12, "Alternative" -> "Greater"]; N[pexact2, 50]
Out[18]=

One-sided "Less" test at q=1/10:

In[19]:=
pexact3 = ResourceFunction["KS2Sample"][120, 150, {80, 70, 40, 80}, 1/10, "Alternative" -> "Less"]; N[pexact3, 50]
Out[19]=

Properties and Relations (1) 

When both samples are identical, every permutation of the pooled sample produces KS statistic 0, so the p-value at any q > 0 is 1:

In[20]:=
x = {1, 2, 3, 4, 5};
ResourceFunction["KS2Sample"][x, x]
Out[21]=

Possible Issues (1) 

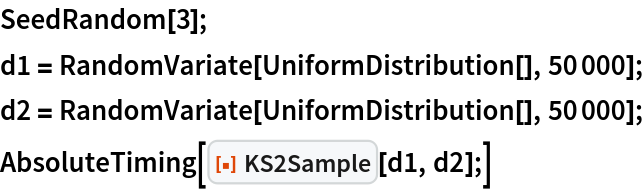
Computation time grows as O(m*n). For m=n=50000 this takes a few seconds; for very large samples consider the R package KSgeneral which uses a compiled C++ implementation:

In[22]:=
SeedRandom[3];
d1 = RandomVariate[UniformDistribution[], 50000];
d2 = RandomVariate[UniformDistribution[], 50000];
AbsoluteTiming[ResourceFunction["KS2Sample"][d1, d2];]
Out[23]=

Neat Examples (6) 

The Titanic dataset is built into Mathematica and contains 1309 passengers whose ages are recorded to one decimal place, producing heavy ties. We test whether the age distribution of survivors differs from that of non-survivors:

Load the Titanic dataset and split by survival status;drop passengers with missing age:

In[24]:=
titanic = Normal@ExampleData[{"Dataset", "Titanic"}];
survived = #["age"] & /@ Select[titanic, #["survived"] === True && NumberQ[#["age"]] &];
notsurvived = #["age"] & /@ Select[titanic, #["survived"] === False && NumberQ[#["age"]] &];
{Length[survived], Length[notsurvived]}
Out[25]=

Top 10 most common ages—heavy natural ties throughout:

In[26]:=
SortBy[Tally[Join[survived, notsurvived]], -Last[#] &][[1 ;; 10]]
Out[26]=

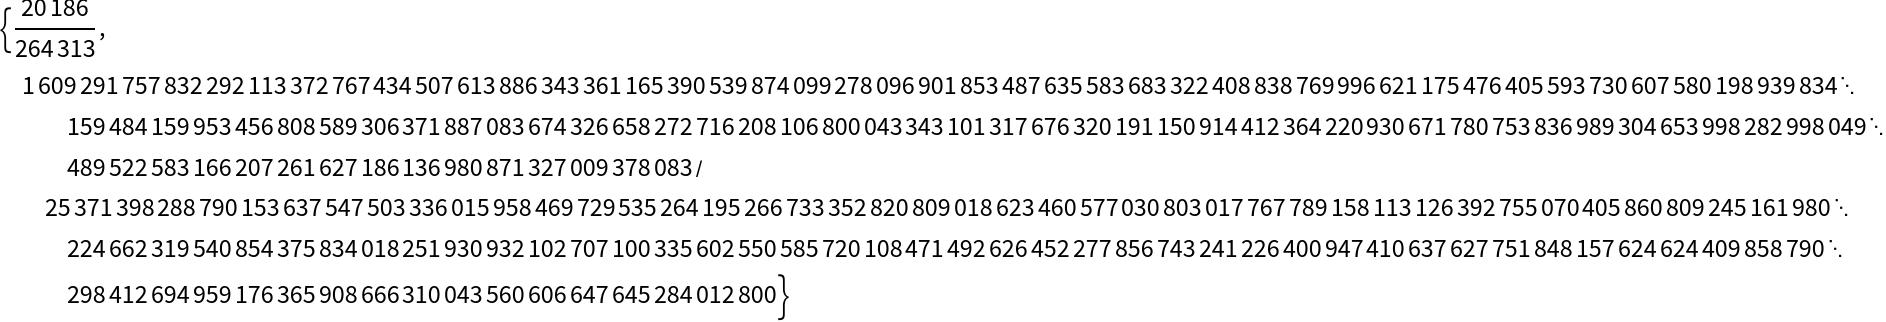
Two-sided unweighted KS test;exact rational p-value:

In[27]:=
{dstat, pval} = ResourceFunction["KS2Sample"][survived, notsurvived]
Out[27]=

30-digit evaluation of the p-value:

In[28]:=
N[pval, 30]
Out[28]=

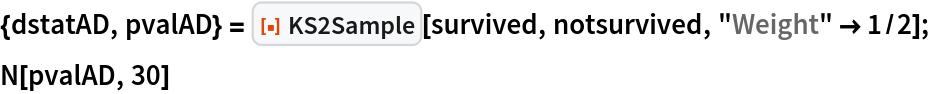
Anderson-Darling weight (ν=1/2):more sensitive to tail differences:

In[29]:=
{dstatAD, pvalAD} = ResourceFunction["KS2Sample"][survived, notsurvived, "Weight" -> 1/2];
N[pvalAD, 30]
Out[30]=

Publisher

Yun Jia

Version History

  • 1.0.0 – 02 October 2026

Source Metadata

Related Resources

Author Notes

The Mathematica implementation uses the original recurrence algorithm of Nikiforov (1994), extended by Dimitrova, Jia, Kaishev (2026) to support arbitrary weight functions and tied observations. It does not use the numerically enhanced Viehmann (2021) variant that is the default in the R package KSgeneral (tail = TRUE). Because Mathematica performs exact rational arithmetic natively, numerical stability is not a concern and the enhanced variant is unnecessary. The returned p-value is an exact rational number. Worst-case computational complexity is O(m·n). For sample sizes in the hundred thousands, evaluation takes a few seconds. For very large samples (m·n > 500,000) and a few jumps, the asymptotic formula of Theorem 2.3 of Dimitrova, Jia, Kaishev (2026) is more efficient, but is not included here.

License Information